voicebench
voicebench measures how a real-time voice agent behaves in a conversation: how fast it answers, whether it stops when you interrupt it, and whether a cough makes it stop talking.
It plays a scripted conversation into your agent, records both sides of the call as audio, and derives every metric from that audio with a voice activity detector. It works with any agent you can reach over a transport: a plain WebSocket that streams PCM, a LiveKit room, a Pipecat bot, or your own adapter.
Install
Install the package from PyPI:
python -m pip install voicebench
Or install the standalone executable, which needs no Python, with the install script:
curl -fsSL https://raw.githubusercontent.com/superintelligenceco/voicebench/main/install.sh | sh
Or run the container image:
docker run --rm ghcr.io/superintelligenceco/voicebench:latest example mock-conversation > demo.yaml
docker run --rm -v "$PWD:/work" ghcr.io/superintelligenceco/voicebench:latest run demo.yaml
Run the demo
voicebench example mock-conversation -O demo.yaml
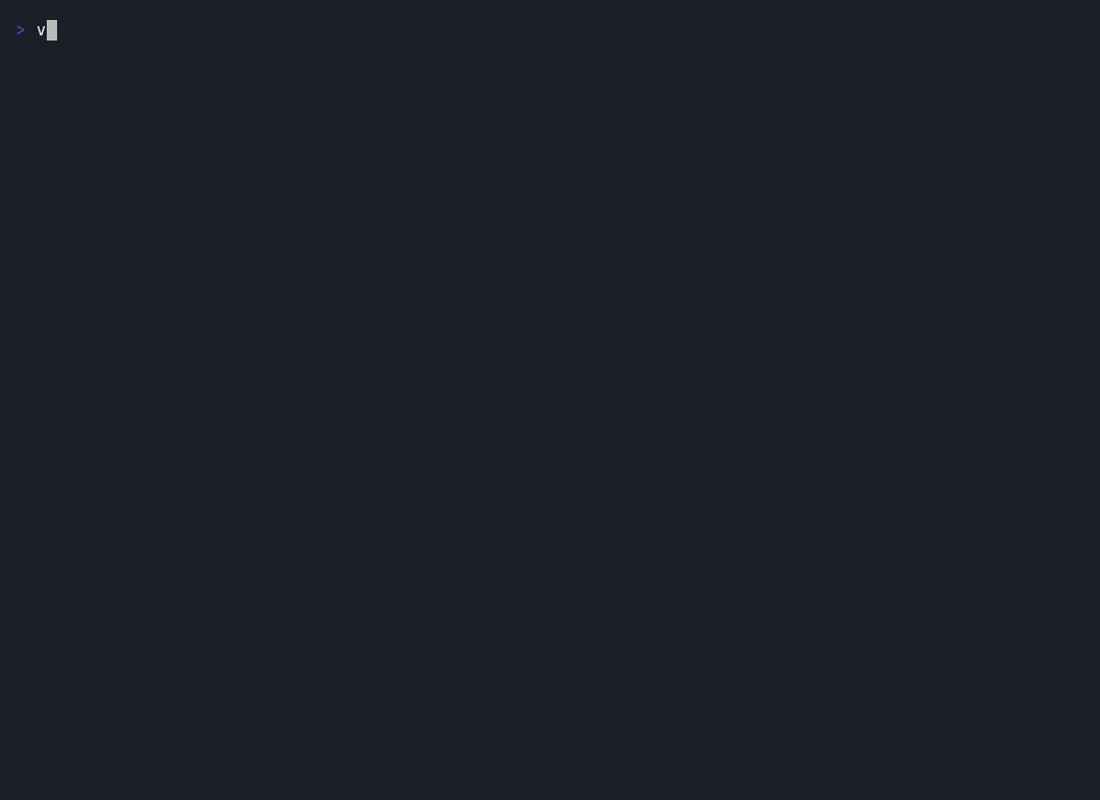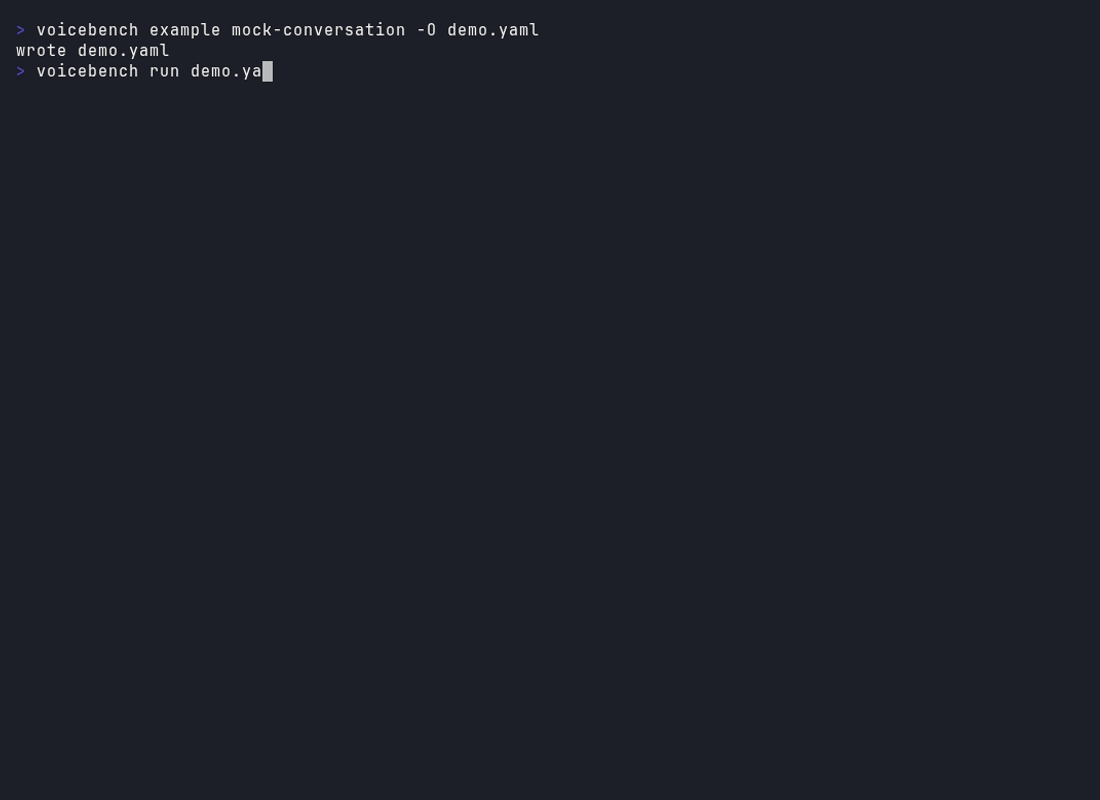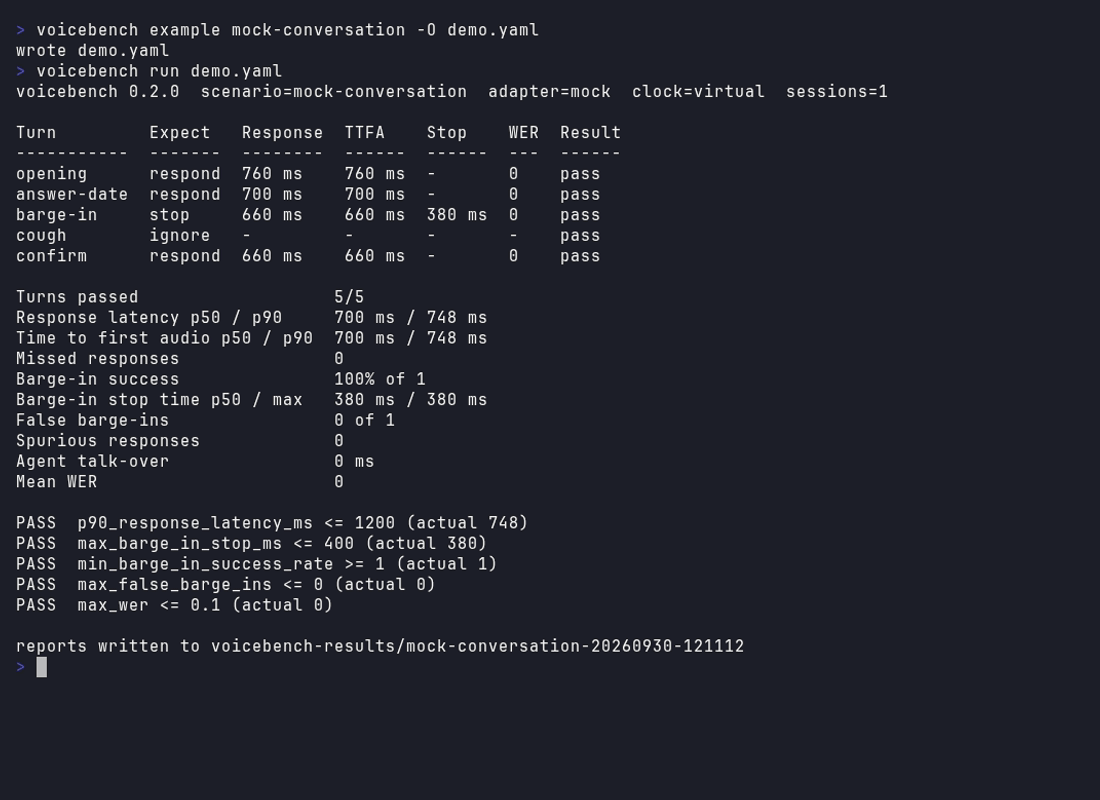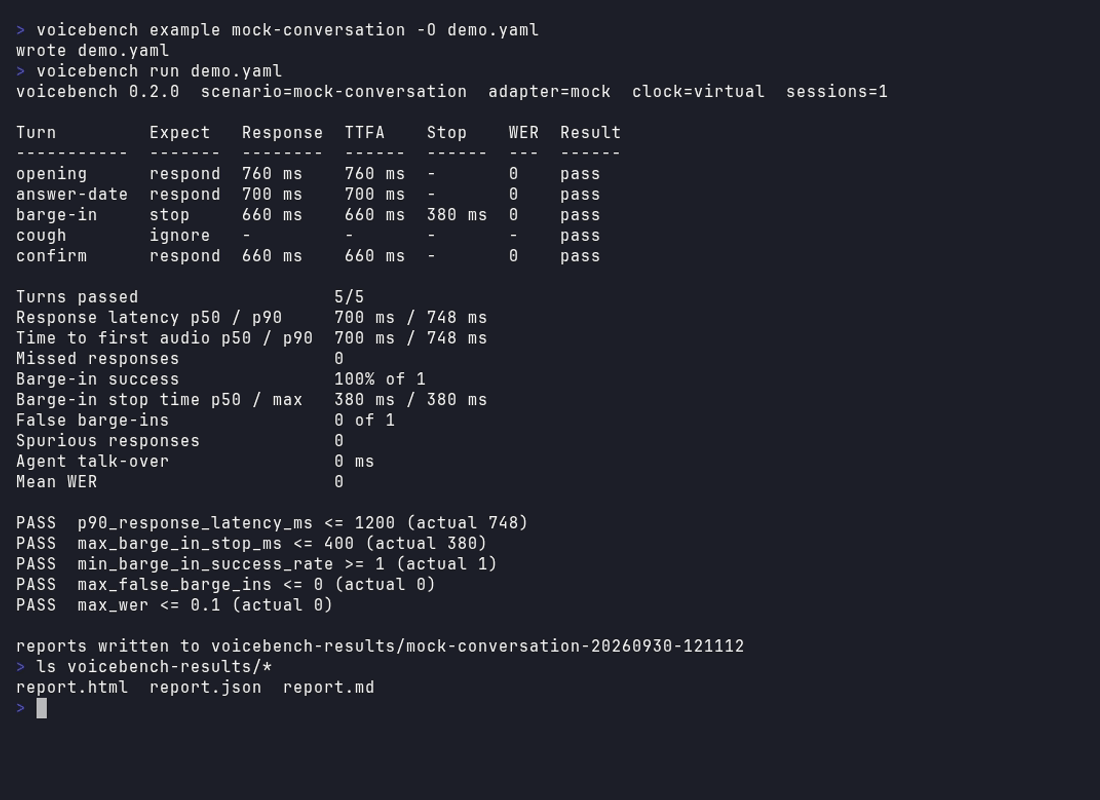
voicebench run demo.yaml
The run writes report.json, report.md, and report.html to voicebench-results/. The bundled mock agent runs on a virtual clock, so the demo finishes in well under a second and gives the same numbers every time.
Next steps
- Architecture shows how a run flows from the scenario to the report.
- Scenarios documents the YAML format and every assertion.
- Metrics explains the VAD and how each metric is computed.
- Adapters documents the adapter interface and the WebSocket protocol.
- FAQ answers common questions.
- Decisions records why voicebench works the way it does.