evalkit
Evals as code for LLM apps and agents. You write tasks and graders in a YAML suite, run them against a model or your own app, and fail the build when quality regresses.
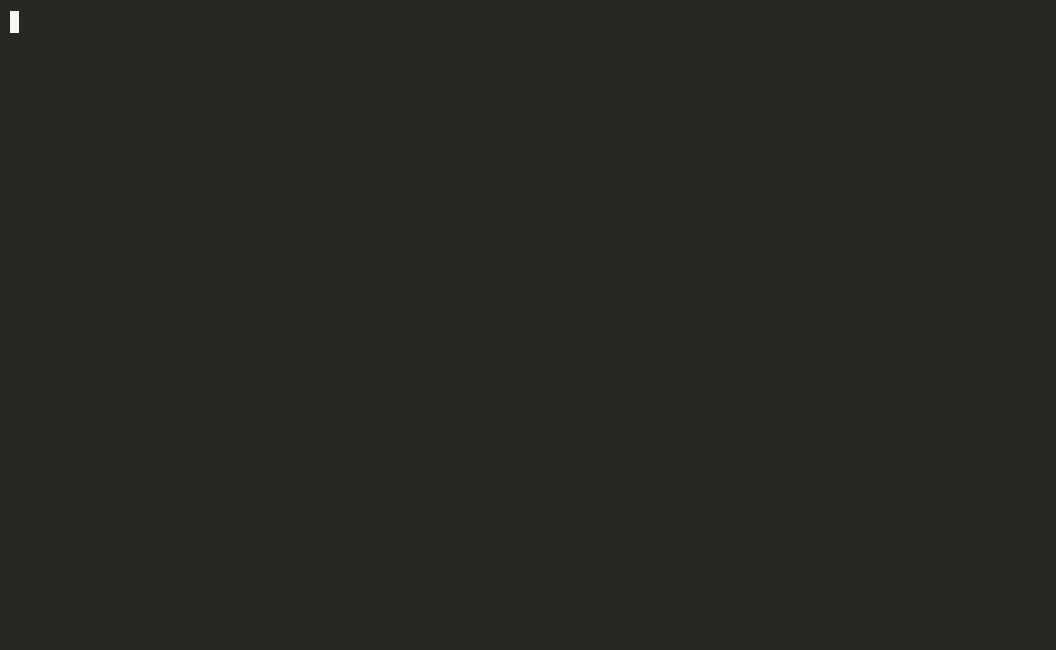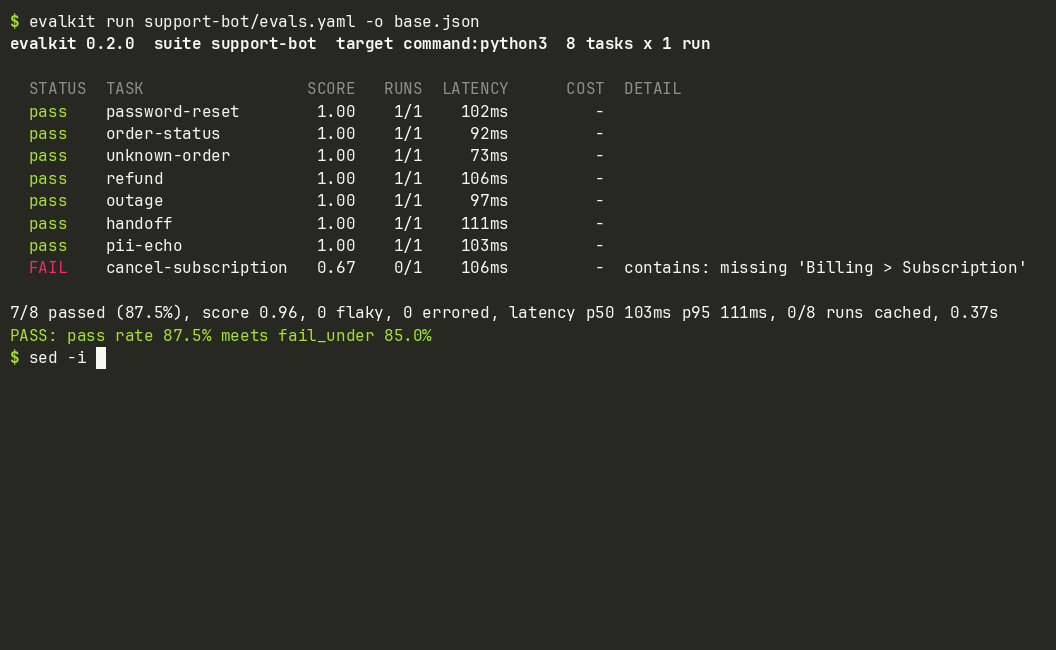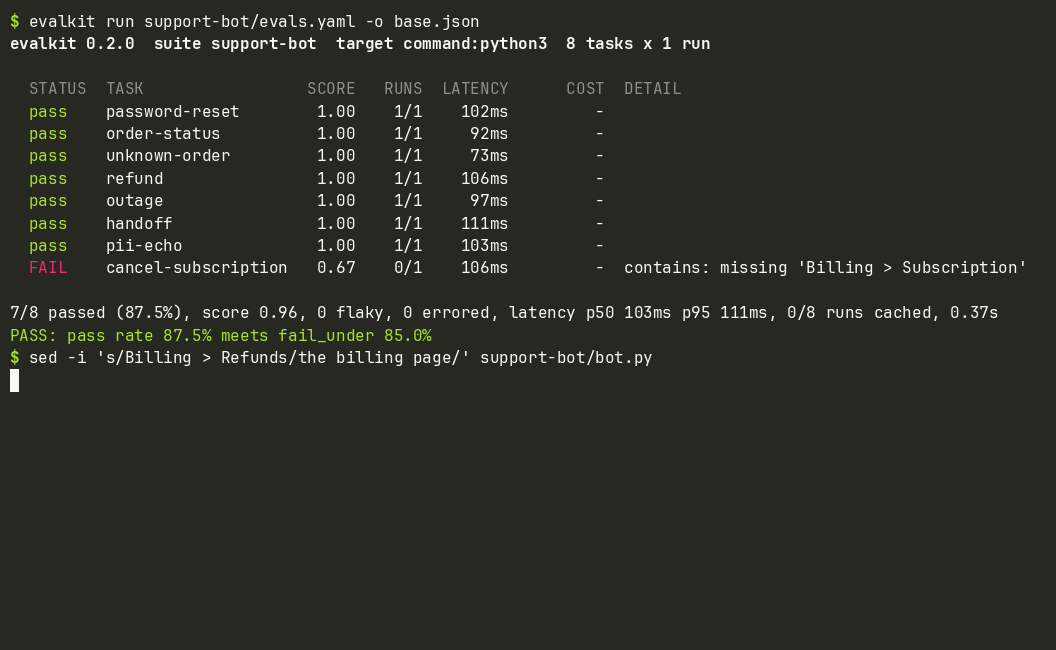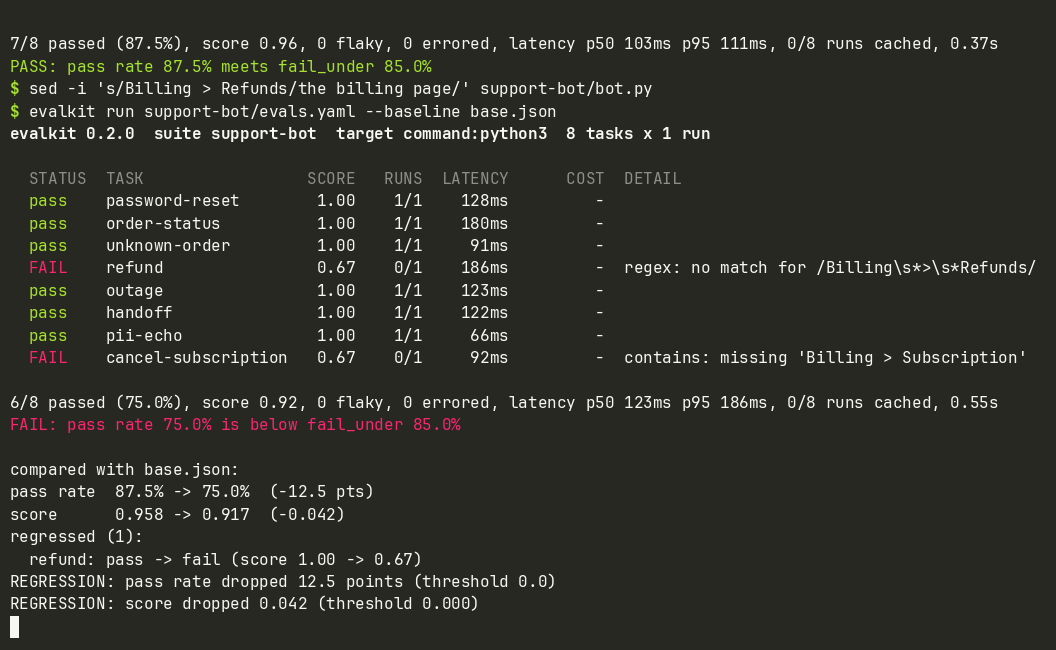
evalkit sends each task to a target, grades the answers, and gives you a results table, JSON and JUnit output, a regression diff against a saved baseline, and a badge. It runs the same on your laptop and in GitHub Actions.
Install
pip install sic-evalkit
The distribution is named sic-evalkit. The command and the Python package are both evalkit.
Where to go next
- Quickstart: run your first suite in a minute, offline.
- Concepts: suites, targets, graders, scoring, repeats, the cache, and baselines.
- CI integration: running evalkit in GitHub Actions and gating pull requests on regressions.
- Command-line reference and suite file reference.
- Architecture and the decision records.
- FAQ.